Updated October 7, 2026, for laravel/ai 1.x and Laravel 13.35. Since 1.0 the SDK saves a failed run’s finished steps, but only when PHP throws, and a default timeout kill never throws. Since 13.34 a timeout warns an
Interruptiblejob first, milliseconds before the kill. The re-runs also found a hole in this post’s own ledger, fixed below. Every run here is on 1.1 unless it says otherwise. See what changed.
You queued the research agent because the tools post told you to. Anything slow belongs on a queue. The docs agree: ->queue() keeps the app “fast and responsive”.
So it runs on a worker now. Same three Firecrawl tools, same database check, plus one crawl start per run. On Haiku a full run took 46 to 98 seconds across both SDK versions. On Sonnet the provider calls alone took 53 to 58 on 0.11.
The worker’s default timeout is 60.
Here is one run with the timeout cut to 20, so it lands on Haiku too, and --tries=2:
10:06:54  attempt 1  step 1  FirecrawlSearch ×3
10:07:01  attempt 1  step 2  FirecrawlScrape, FirecrawlCrawl
10:07:23  attempt 1  job.timed_out  timeout=20
10:07:23  attempt 1  Worker STOPPED  Job timed out
10:08:20  attempt 2  step 1  messages=1
10:08:24  attempt 2  step 1  FirecrawlSearch ×3
10:08:31  attempt 2  step 2  FirecrawlScrape, FirecrawlCrawl
10:08:46  attempt 2  step 3  DatabaseQueryTool
10:08:48  attempt 2  step 4  DatabaseQueryTool
10:09:06  attempt 2  then    text_chars=4577
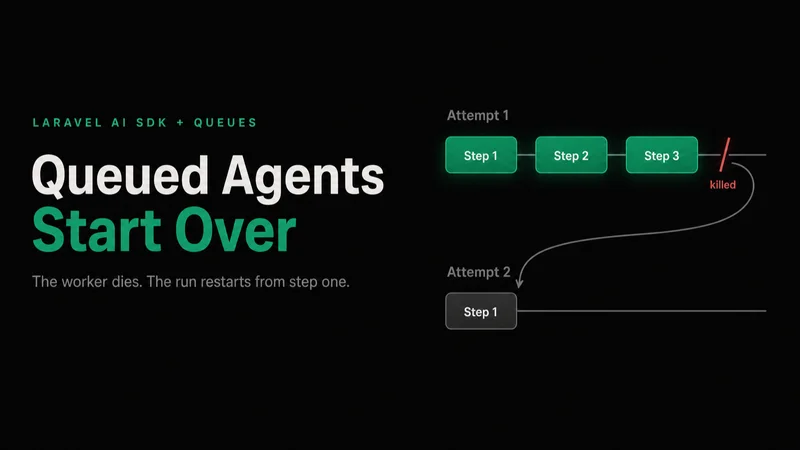
Attempt 1 ran four tools and sent a crawl request. Then the worker killed itself.
Attempt 2 knew none of that. It ran seven more tools and crawled a different site. None of its calls repeated attempt 1’s arguments, because the model planned from scratch.
Nothing in your app recorded that attempt 1 happened.
The job the SDK dispatches
->queue() does one thing:
return new QueuedAgentResponse(
    InvokeAgent::dispatch($this, $prompt, $attachments, $provider, $model)
);
And Laravel\Ai\Jobs\InvokeAgent, minus its docblocks and displayName():
class InvokeAgent implements ShouldQueue
{
    use Concerns\InvokesQueuedResponseCallbacks;
    use Queueable;

    public function __construct(
        public Agent $agent,
        public Decisions|string $prompt = '',
        public array $attachments = [],
        public Lab|array|string|null $provider = null,
        public ?string $model = null) {}

    public function handle(): void
    {
        $this->withCallbacks(fn (): AgentResponse => $this->agent->prompt(
            $this->prompt, $this->attachments, $this->provider, $this->model
        ));
    }
}
No $timeout. No $tries. No $backoff. No ShouldBeUnique. No Interruptible. Still none on 1.1.
Your agent object, tools and all, serialized into the payload, and one call to prompt().
So the worker decides everything. queue:work defaults to --timeout=60 --tries=1.
Horizon’s supervisor command defaults to --tries=0, and zero means unlimited, which oussama-mater.tech learned the hard way. The config/horizon.php that Horizon publishes sets 'tries' => 1. Drop that line and you are back to zero.
Same job, two settings, two different disasters.
What happens at second 60
The worker arms pcntl_alarm before every job. On Laravel 13.35, when it fires, the handler does five things in order.
- New in 13.34, it first calls
interrupted(SIGALRM)on the job, if the job implementsInterruptible. - It fails the job if this attempt was its last.
- It dispatches
JobTimedOut. - It dispatches
WorkerStoppingwith the reasonTimedOut. - It sends
SIGKILLto its own process.
InvokeAgent is not Interruptible, so the new first step skips it.
With --tries=1, the job fails before the kill. The SDK’s catch callback runs with a TimeoutExceededException, and then the process dies.
That is the pure-default run, and on Sonnet it is not a maybe. On laravel/ai 0.11, same agent, queue:work with no flags: two searches, a scrape, the database check, a crawl started at 13:05:49, then the answer step. The alarm fired at 13:06:34, 78 seconds in, while the model was writing.
catch fired. failed_jobs got a row. The crawl kept running on Firecrawl’s side with nobody left to collect it.
With any other tries, nothing fails the job. The process dies with the job still reserved. retry_after is 90 seconds by default, so 90 seconds after the original reservation another worker picks it up and runs handle() from the top.
In the run above, the worker reserved attempt 1 at 10:06:50. Attempt 2 started at 10:08:20. Ninety seconds.
With zero tries, that loop has no end. Laravel 13.34 added #[CountCrashesAsExceptions], which counts an attempt that never finished against the job’s $maxExceptions. It caps how many crashes a job survives. It does not stop the tools from running again, and it goes on the job class, so InvokeAgent cannot opt in.
A kill is not a failure
The agent above uses RemembersConversations. Since laravel/ai 1.0 its middleware wraps the run like this:
try {
    $response = $next($prompt);
} catch (Throwable $exception) {
    $this->rememberFailedTurn($prompt, $exception, $pendingConversationId);

    throw $exception;
}

return $response->then(function (AgentResponse $completedResponse) use (/* ... */): void {
    // ...
    $userMessageId = $this->openTurn($agent, $prompt, $pendingConversationId);
    $assistantMessageId = $this->store->storeAssistantMessage(/* ... */);
});
That catch block is a real fix. When a step throws after an earlier step finished, the SDK stores the user message and an assistant row with the status failed. The row’s steps column holds every step that finished, tool results included. The docs say a turn that failed partway through “is stored as Failed along with the steps it had already completed”.
A catch block runs when PHP throws. By default the timeout handler throws nothing.
It sends SIGKILL to its own process, and no PHP code runs after a SIGKILL. Not the catch. Not the then.
13.34 also added Worker::$killOnTimeout. Set it to false and the handler throws TimeoutExceededException instead of killing. I have not run that.
In the run above, agent_conversation_messages had 218 rows before attempt 1 and 218 rows after it. The default timeout, an out-of-memory kill and kill -9 all end the same way. A SIGKILL is not a failed turn.
Attempt 2 loads the conversation, finds nothing, appends the prompt, and starts over.
If your agent is not Conversational, there is no store at all. The only outputs of a queued run are the then callbacks, and those run after prompt() returns. Kill the worker and the run never happened, except on the provider’s invoice and inside every tool that wrote something.
One of those tools was FirecrawlCrawl, which I wrote. In a run on 0.11 it reported cURL error 28: Operation timed out after 30000 milliseconds. Firecrawl’s active-crawl endpoint listed that crawl 42 seconds after the request started.
The tool told the model it failed. The crawl was running. The timeout hit the response, not the action, and it happened without a worker kill at all.
The step cap is not this bug
You will reach for MaxSteps. It is the wrong tool for this.
When the loop hits its last step and the model still asks for a tool, the SDK does not run it. It writes a placeholder result instead:
The agent reached its maximum number of steps without running this tool call.The SDK marks that result failed, the run returns normally, and the history saves as usual. A step-capped run is a finished run. The cost-math post has a Haiku run that ended this way, with a DatabaseQueryTool call on step 5 that never executed.
The cap protects you from the model. It does nothing about the worker.
The SDK already knows how to do this
Read the human-approval section of the docs and you find this sentence:
Laravel stores the result of an approved tool before asking the model to continue. If generation then fails, the approval has already been resolved.
That is the fix. Persist the tool result before the next model call, so a crash after the tool ran costs nothing on retry.
The implementation is real. On a resume, the loop executes the approved tools before its first step. It hands the results to a recorder that writes them into the paused conversation row, inside a transaction, with lockForUpdate().
The repo has a test named for it: a resume that fails after the tool runs does not re-execute the tool on retry. Tool runs once. Provider returns 500. The same decisions go in again. The tool count is still one.
Now count how many of your agent’s tool calls go through an approval. For the research agent, none.
So 1.x writes tool results in two places. The approval path writes them before the next model call. The failed-turn path writes them after a throw. A SIGKILL reaches neither.
That tells you what to build for the other calls. Write each tool result down before the loop asks the model what to do next.
The key comes from your domain
The tool Request has a method for this, and its docblock says so:
/**
 * Get the stable provider tool-call ID, usable as an external idempotency key.
 */
public function toolCallId(): ?string
Stable within one invocation. On an approval resume the SDK replays the same paused turn, so the id matches.
On a job retry the model plans again and the provider mints new ids. In the run above, attempt 1’s first search asked for “Laravel queued jobs LLM agent timeouts retries”. Attempt 2’s added “duplicate tool calls”. Different id, different arguments, same intent.
So the key has to come from the job, not from the model. My first ledger used the run, the tool, and a hash of every argument. The 1.1 re-runs broke it.
When a worker dies mid-step, the resume plans that step again, and the model rewrites what it typed. I killed the worker during a crawl three times. The resumed model asked for the crawl again every time, and never with the same arguments:
| Kill | Ledger key | The resumed crawl | Crawls sent |
|---|---|---|---|
| First | every argument | same URL, reworded prompt | 2 |
| Second | the url argument | a different URL | 2 |
| Third | the run | a different URL, reworded prompt | 1 |
toolCallId() is the wrong key. So is a hash of everything the model typed, and so is any argument the model gets to choose.
Key a side effect on what makes it the same side effect in your domain. This agent’s instructions ask for one crawl per run, so the run is the key. A refund tool keys on the order. A scrape keys on its URL, because the same page is the same read.
Claim before you execute
Wrap each tool. The wrapper inserts a claim row first, runs the tool second, stores the result third. The unique index is the lock.
use Illuminate\Contracts\JsonSchema\JsonSchema;
use Illuminate\Database\UniqueConstraintViolationException;
use Illuminate\Support\Facades\DB;
use Laravel\Ai\Contracts\Tool;
use Laravel\Ai\Tools\Request;
use Laravel\Ai\Tools\ToolNameResolver;
use Stringable;
use Throwable;

class IdempotentTool implements Tool
{
    /**
     * @param  list<string>|null  $keyArguments  null: every argument. []: none, the run is the key.
     */
    public function __construct(
        private readonly Tool $tool,
        private readonly string $runKey,
        private readonly ?array $keyArguments = null,
        private readonly bool $atMostOnce = false,
    ) {}

    public function name(): string
    {
        return ToolNameResolver::resolve($this->tool);
    }

    public function description(): Stringable|string
    {
        return $this->tool->description();
    }

    public function schema(JsonSchema $schema): array
    {
        return $this->tool->schema($schema);
    }

    public function handle(Request $request): Stringable|string
    {
        $args = $request->all();
        ksort($args);

        $key = $this->keyArguments === null ? $args : array_intersect_key($args, array_flip($this->keyArguments));

        $claim = [
            'run_key' => $this->runKey,
            'tool' => $this->name(),
            'args_sha' => sha1(json_encode($key, JSON_UNESCAPED_SLASHES | JSON_UNESCAPED_UNICODE)),
        ];

        try {
            DB::table('agent_tool_invocations')->insert([
                ...$claim,
                'args' => json_encode($args, JSON_UNESCAPED_SLASHES | JSON_UNESCAPED_UNICODE),
                'status' => 'claimed',
                'created_at' => now(),
                'updated_at' => now(),
            ]);
        } catch (UniqueConstraintViolationException) {
            $existing = DB::table('agent_tool_invocations')->where($claim)->first();

            if ($existing->status === 'done') {
                return $existing->result;
            }

            // Claimed, no result: the last attempt died inside this call.
            // For a paid side effect, a second charge is worse than a missing result.
            if ($this->atMostOnce && $existing->status === 'claimed') {
                return 'A previous attempt of this run started this call and was interrupted before a result was recorded, so it may or may not have run. Do not call it again.';
            }

            // Safe to repeat: run it again and take over the row.
        }

        try {
            $result = (string) $this->tool->handle($request);
        } catch (Throwable $e) {
            DB::table('agent_tool_invocations')->where($claim)->update(['status' => 'failed', 'updated_at' => now()]);

            throw $e;
        }

        DB::table('agent_tool_invocations')->where($claim)->update([
            'status' => 'done',
            'result' => $result,
            'updated_at' => now(),
        ]);

        return $result;
    }
}
The name() method matters. The SDK resolves a tool’s name from name() when it exists and from the class basename when it does not. Without it, the model would see four tools called IdempotentTool.
The order matters more. Insert, then execute, then update.
Execute first and record second, and a crash between the two leaves no trace, so the retry runs the tool again. buildmvpfast calls this “executing before claiming” and says they have seen it four times in production codebases. If you would rather install than build, Laravel Rick 0.1.0 is a workflow engine that claims interrupted-run recovery and protection against repeating ambiguous paid requests.
Claim first, and the worst case is a claimed row with no result. The worker died inside the call, and nobody knows whether it ran.
For a read, run it again. For a paid side effect, running it again is a second charge. So an atMostOnce tool answers in the SDK’s own words for an interrupted call and runs nothing.
The migration is a table with run_key, tool, args_sha, args, status, result, and unique(['run_key', 'tool', 'args_sha']). The hash covers only the key. The args column keeps everything the model sent.
Checkpoint before every step, replay on retry
The ledger stops a tool from running twice. It does not stop the retry from paying for steps 1 and 2 again, and it cannot tell the model what those steps found.
For that you need the history. The SDK hands it to you before every step:
class StartingStep
{
    /**
     * @param  Message[]  $messages  The messages being sent for this step, including the tool results of the steps before it.
     */
    public function __construct(
        public string $invocationId,
        public int $stepNumber,
        // ...
        public array $messages,
        // ...
    ) {}
}
That array is the full replayable transcript so far. Store it, keyed by the run:
use Illuminate\Support\Facades\DB;
use Laravel\Ai\Events\StartingStep;

class StepCheckpoint
{
    public function starting(StartingStep $event): void
    {
        $runKey = CurrentRun::key();

        if ($runKey === null) {
            return;
        }

        DB::table('agent_step_checkpoints')->updateOrInsert(
            ['run_key' => $runKey, 'step' => $event->stepNumber + 1],
            [
                'message_count' => count($event->messages),
                'messages' => base64_encode(serialize($event->messages)),
                'created_at' => now(),
                'updated_at' => now(),
            ],
        );

        if (CurrentRun::stopRequested()) {
            throw RunInterrupted::beforeStep($event->stepNumber + 1, SIGTERM);
        }
    }

    public static function latest(string $runKey): ?array
    {
        // Step numbers restart at 1 on every attempt, so the newest checkpoint
        // is the one with the most history, not the highest step.
        $row = DB::table('agent_step_checkpoints')
            ->where('run_key', $runKey)
            ->orderByDesc('message_count')
            ->orderByDesc('id')
            ->first();

        return $row === null ? null : ['step' => (int) $row->step, 'messages' => unserialize(base64_decode($row->messages))];
    }
}
CurrentRun is a static holder for the run key and a stop flag. A worker runs one job at a time. The SDK’s events carry an invocation id but not the job, so the run key lives in process-local state. RunInterrupted is a RuntimeException with a message. Register the listener in a service provider: Event::listen(StartingStep::class, [StepCheckpoint::class, 'starting']).
The messages are plain value objects: UserMessage, AssistantMessage with a collection of ToolCall, ToolResultMessage with a collection of ToolResult. serialize() round-trips them. The base64 is there because serialized protected properties carry NUL bytes. In one run SQLite’s length() reported 345 bytes for a 49 KB checkpoint.
The checkpoint sits at the start of a step. On resume the model plans the step that was running again. The ledger key decides whether that step sends a second crawl.
Then the agent replays the checkpoint and declares its keys. Implement Conversational and return the checkpoint from messages():
use App\Ai\Durable\IdempotentTool;
use App\Ai\Durable\StepCheckpoint;
use Laravel\Ai\Contracts\Tool;
use Shipfastlabs\Toolkit\Firecrawl\FirecrawlCrawl;
use Shipfastlabs\Toolkit\Firecrawl\FirecrawlScrape;

class DurableResearchAgent extends QueuedResearchAgent
{
    // One crawl per run, whatever URL the model picks. The same page is the same read.
    private const KEY_ARGUMENTS = [
        FirecrawlCrawl::class => [],
        FirecrawlScrape::class => ['url'],
    ];

    private const AT_MOST_ONCE = [
        FirecrawlCrawl::class,
    ];

    public function __construct(public readonly string $runKey)
    {
        parent::__construct();
    }

    public function tools(): iterable
    {
        foreach (parent::tools() as $tool) {
            yield $tool instanceof Tool
                ? new IdempotentTool(
                    $tool,
                    $this->runKey,
                    keyArguments: self::KEY_ARGUMENTS[$tool::class] ?? null,
                    atMostOnce: in_array($tool::class, self::AT_MOST_ONCE, true),
                )
                : $tool;
        }
    }

    public function messages(): iterable
    {
        return StepCheckpoint::latest($this->runKey)['messages'] ?? [];
    }

    public function isResuming(): bool
    {
        return StepCheckpoint::latest($this->runKey) !== null;
    }
}
The declarations live in the agent because the Firecrawl tools are package code. Every tool not listed keys on all its arguments and re-runs a call that died.
The loop builds its message list as your messages() followed by a new UserMessage with the prompt. The checkpoint already starts with the original prompt. Send it again on a retry and the model sees its own work followed by the original task, and starts over.
So on a retry the job below sends a continuation prompt instead.
This is what the approval docs tell you to do after a failed resume: “continue the conversation with a normal text prompt”. Same mechanism, no approval required.
Own the job
->queue() gives you InvokeAgent. Write your own instead. Every declaration in it is one the SDK’s job left out.
use App\Ai\Agents\DurableResearchAgent;
use App\Ai\Durable\CurrentRun;
use Illuminate\Contracts\Queue\Interruptible;
use Illuminate\Contracts\Queue\ShouldBeUnique;
use Illuminate\Contracts\Queue\ShouldQueue;
use Illuminate\Foundation\Queue\Queueable;
use Illuminate\Support\Facades\Storage;

class RunDurableResearch implements ShouldQueue, ShouldBeUnique, Interruptible
{
    use Queueable;

    public int $timeout = 240;

    public int $tries = 3;

    public array $backoff = [5, 30];

    public int $uniqueFor = 600;

    public function __construct(
        public readonly string $runKey,
        public readonly string $topic,
        public readonly string $model = 'claude-haiku-4-5-20251001',
    ) {}

    public function uniqueId(): string
    {
        return $this->runKey;
    }

    public function handle(): void
    {
        CurrentRun::begin($this->runKey);

        $agent = new DurableResearchAgent($this->runKey);

        $prompt = $agent->isResuming()
            ? 'The previous worker stopped before you finished. Continue from where you were. Do not repeat tool calls whose results are already in this conversation.'
            : "Research this blog topic and recommend angles we haven't covered: {$this->topic}";

        $response = $agent->prompt($prompt, provider: 'anthropic', model: $this->model, timeout: 120);

        Storage::put("runs/{$this->runKey}-result.md", $response->text);
    }

    public function interrupted(int $signal): void
    {
        CurrentRun::requestStop();
    }
}
Four things in there.
The timeout clears the slowest step. The longest recorded run took 98 seconds, on 0.11. The per-step provider timeout is 120, so 240 leaves room for one step to hit its limit. A timeout that lands mid-step throws that step’s work away. Keep retry_after on the connection above $timeout, or a second worker picks the job up while the first is still running it. That is oussama’s gotcha #4 and Deploynix’s double bill, and it applies unchanged.
Tries are explicit. Three, with a backoff. The retry that resumes from the checkpoint is a decision you made, not Horizon’s zero.
One run per key. ShouldBeUnique on the run key stops a double dispatch from starting two runs that fight over one ledger. Set uniqueFor. A unique lock with no expiry survives a SIGKILL forever, which is oussama’s gotcha #3.
Interruptible. Laravel 13.31 added this contract and the JobInterrupted event. When the worker receives SIGTERM, SIGINT or SIGQUIT while your job is running, it calls interrupted($signal) on the job. Only on jobs that implement the contract, so the hook is unreachable from ->queue().
Here it sets a flag. The StepCheckpoint listener checks that flag at the next step boundary, after writing the checkpoint and before the next provider call, and throws. The exception leaves the loop cleanly. The worker releases the job with the backoff, and the retry resumes from the checkpoint.
Since 13.34 the timeout handler calls interrupted() too, with SIGALRM. The last run below shows why that does not help.
Kill it again
Same topic, same tools, same worker. This time the job is RunDurableResearch, and the script sends kill -9 to the worker twenty seconds in. That is the same signal an out-of-memory kill sends.
12:19:19  attempt 1  durable.start   resuming=false
12:19:23  attempt 1  step 1  FirecrawlSearch ×3                  ledger rows 1-3
12:19:32  attempt 1  step 2  FirecrawlScrape ×2, FirecrawlCrawl  ledger rows 4-6
12:19:38  attempt 1  step 3  starting, messages=5    checkpoint written
          kill -9                                     (mid provider call)
13:08:20  attempt 2  durable.start   resuming=true
13:08:20  attempt 2  step 1  starting, messages=6
13:08:22  attempt 2  step 1  DatabaseQueryTool                   ledger row 7
13:08:44  attempt 2  durable.done    text_chars=5977
Attempt 2 loaded five messages from the checkpoint and added the continuation prompt. Its first model call asked for the one tool attempt 1 had not called. Not the searches. Not the scrapes. Not the crawl.
Seven ledger rows, each executed once. The 49-minute gap is me starting the second worker late. The checkpoint does not expire.
The SDK’s job in the opening run: eleven tool calls, two crawl requests, one answer. This one: seven, one crawl, nothing run twice.
Now the kill the ledger key exists for. The script waits for the crawl’s claim row and kills the worker during the crawl request:
13:09:18  attempt 1  step 2  FirecrawlScrape, FirecrawlCrawl
13:09:19  attempt 1  FirecrawlCrawl  url=mujahidabbas.dev        claimed
          kill -9                                     (mid crawl request)
13:10:40  attempt 2  step 1  starting, messages=4
13:10:45  attempt 2  FirecrawlScrape                             ledger.replayed
13:10:45  attempt 2  FirecrawlCrawl  url=mujahidabbas.dev/blog   ledger.unknown, not sent
13:10:45  attempt 2  DatabaseQueryTool
13:11:01  attempt 2  durable.done
The checkpoint predates step 2, so attempt 2 planned step 2 again. It asked for the scrape with the same URL and got the stored result in 2 ms. It asked for the crawl with a new URL and a new prompt. That hit the run’s claim and got the interrupted-call message, not a second crawl. Its answer reported the crawl as interrupted, with no id.
One crawl request for the run. Whether Firecrawl started it, nobody knows, and the ledger says exactly that.
Now the deploy case. Same job, kill -TERM at twenty seconds, which is what queue:restart, horizon:terminate and every process supervisor send first.
10:11:00  attempt 1  durable.start   resuming=false
10:11:03  attempt 1  step 1  FirecrawlSearch ×3
10:11:13  attempt 1  step 2  FirecrawlScrape ×3, FirecrawlCrawl
          kill -TERM                                  (20 s in, mid crawl request)
10:11:31  attempt 1  worker.interrupted  signal=15
10:11:31  attempt 1  step 3  starting, messages=5    checkpoint written
10:11:31  attempt 1  RunInterrupted: stopping before step 3
10:11:31  attempt 1  job.released  backoff=5
10:11:31  attempt 1  Worker STOPPED  Interrupted
10:11:37  attempt 2  step 1  starting, messages=6
10:11:39  attempt 2  step 1  DatabaseQueryTool
10:12:05  attempt 2  durable.done    text_chars=7140
The signal arrived during the crawl request. The handler set the flag, the crawl returned, the checkpoint for step 3 went to disk with every result, and the loop threw. Five seconds later a new worker loaded the history, ran the one query left, and wrote the answer.
Eight tool executions, one answer, and a stop that landed between steps. On 1.x the throw also fires AgentFailed, and a remembered agent would write a failed turn. This one keeps its history in the checkpoint and writes none.
The signal took a while to land: SIGTERM at 20 seconds, handled at 31. PHP handles a signal when it gets control back, which in practice is when the in-flight HTTP call returns.
Your stop is as prompt as your slowest tool. That is an argument for HTTP timeouts on your tools, not against the pattern.
Last, the timeout. Same job with $timeout = 20:
10:12:25  attempt 1  durable.interrupted  signal=14
10:12:25  attempt 1  job.timed_out                     4 ms later
10:13:35  attempt 2  durable.start   resuming=true
10:13:47  attempt 2  step 4  starting, messages=10
10:14:06  attempt 2  durable.interrupted  signal=14    alarm due 10:13:55
10:14:06  attempt 2  job.timed_out
10:15:05  attempt 3  durable.start   resuming=true
10:15:23  attempt 3  durable.done    tool_calls=0
The kill came 6 ms after interrupted(). No step boundary in between, so the flag did nothing.
Attempt 2 is worse. Its alarm was due at 10:13:55, during step 4’s provider call. PHP saw it at 10:14:06, when that 19-second generation came back.
The handler killed the worker, and the finished generation, already billed, went with it. Attempt 3 generated it again from the checkpoint.
So set $timeout well above your slowest single step. The checkpoint saves the run, and you still pay twice for the step the kill cut off.
Log why it died
Since 13.30, queue:work prints the reason a worker stopped as its last line. You saw it above: Worker STOPPED Job timed out.
The WorkerStopping event carries the same WorkerStopReason, plus the exit status, the jobs processed, and the memory in use. One listener, one line per stop, and “the agent job disappeared” becomes “timed out on attempt 2 with 38 MB in use”.
Put it next to the StepCompleted rows from the cost-math post and every death has a step number.
What this gives you
You can queue a multi-step agent and kill the worker at any point.
The retry finds the tool results on disk and does not run them again. A call the worker died inside runs again if it reads, and not at all if it charges. The retry finds the history on disk and does not re-plan from the prompt. A deploy signal stops it between steps. A timeout still kills it, and the retry resumes from the checkpoint anyway.
The SDK ships the events that make all of this possible and a job that uses none of them. Read the approval path, build it for the rest of your tools, key every side effect on your domain, and stop paying for step 1 twice.
The ledger, the checkpoint, the job and the kill script are on the ai-1x branch of the companion repo, laravel-ai-research-agent. Run scripts/kill-worker-demo.sh sigkill and watch it resume.
What changed
October 7, 2026, for laravel/ai 1.x and Laravel 13.35:
- Every run is re-measured on laravel/ai 1.1. The few 0.11 numbers left say so.
- “Nothing from the run survives” became “A kill is not a failure”. Since 1.0 the SDK saves a failed run’s finished steps, but only when PHP throws. A default timeout is a
SIGKILLand throws nothing. - The timeout section covers the
interrupted(SIGALRM)call and$killOnTimeoutfrom 13.34. The kill lands 6 ms afterinterrupted(), so a stop flag never acts on a timeout. - New: a timeout can throw away a finished, billed generation. The job’s
$timeoutnow has to clear the slowest single step. - The ledger fix. The old ledger hashed every argument, and on resume the model reworded the crawl, so it ran twice. The ledger now keys each side effect on your domain and never repeats an interrupted crawl.
- Smaller fixes: the Horizon
triesdefault now accounts for its published config. The post adds#[CountCrashesAsExceptions]and the 1.x storage columns, and no longer calls the approval path the only one that saves tool results. - The companion code is public on the
ai-1xbranch, withretry_afterabove the job’s$timeout. The previous version linked the repo before that code was pushed.